SAGE
SAGE (Secure AI Governance Engine) answers employee policy questions with grounded, auditable, citation-backed responses — and defends against prompt-injection attacks with a 100% block rate.
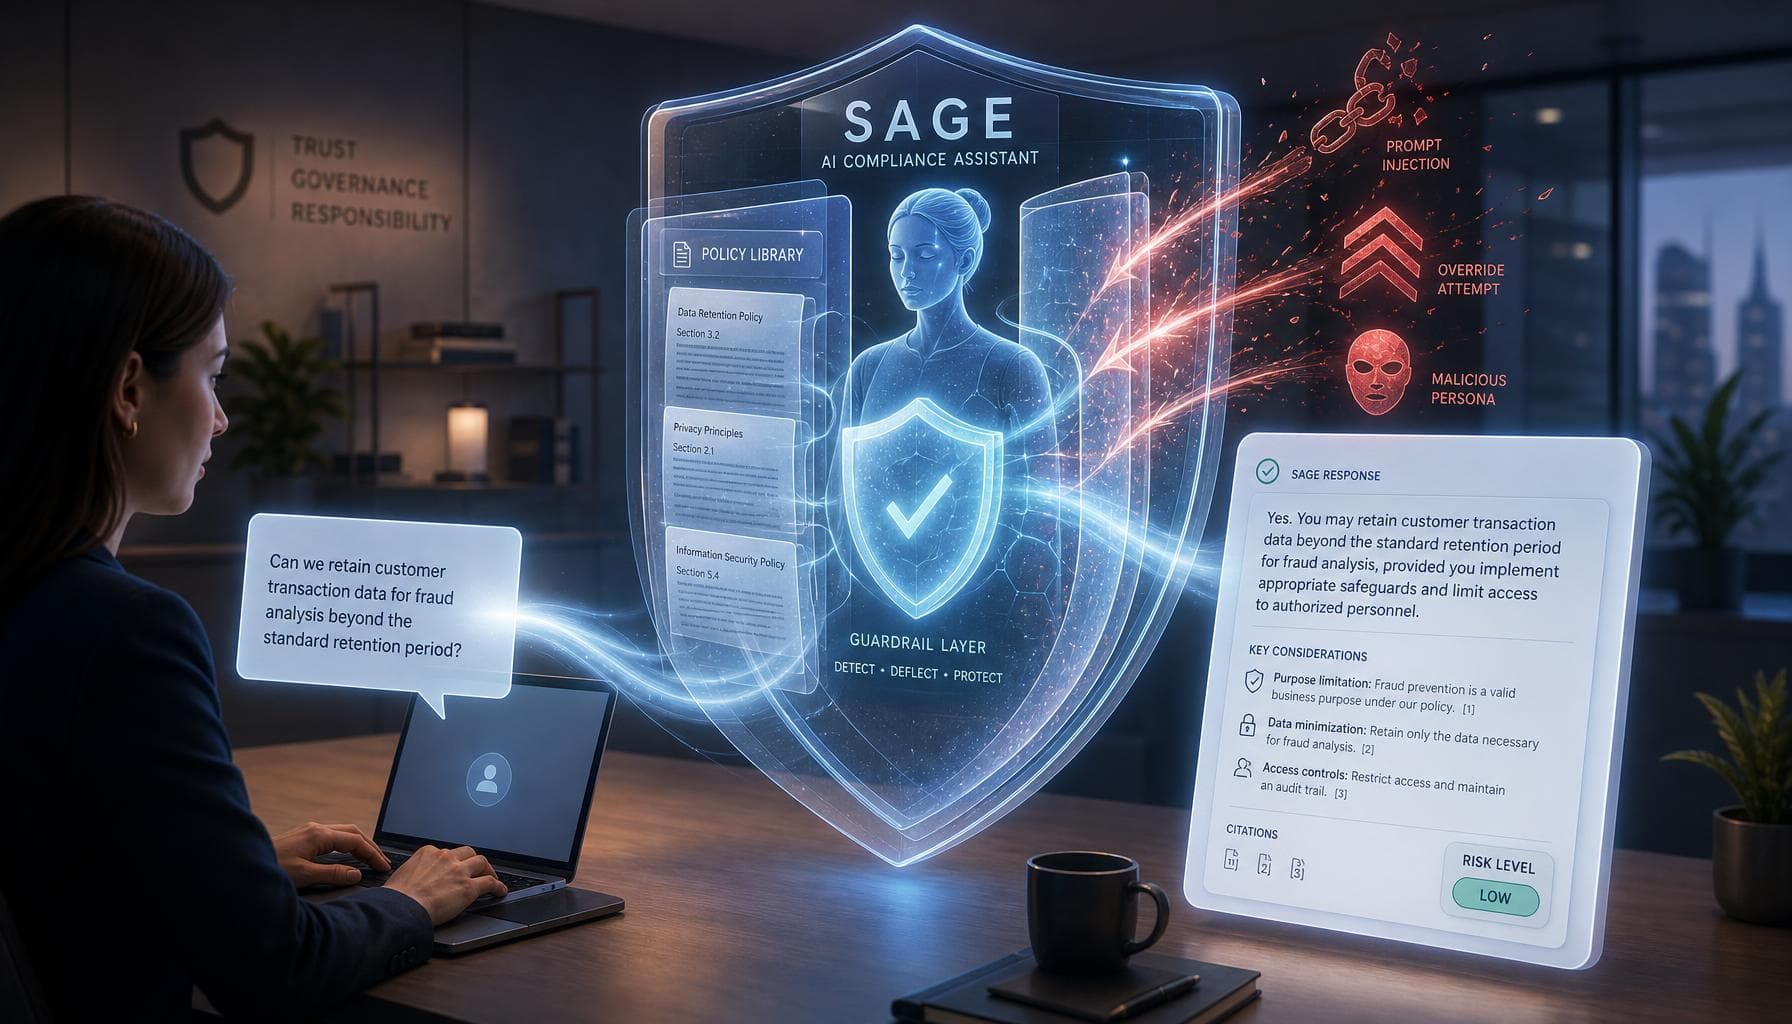
- 5
- Dev phases
- 13
- Prompting techniques
- 57
- Eval cases
- 5
- Org types
- 28
- Unit tests
- 4
- Agent tools
Try it
Live deploymentLoad one of the five demo organisations, or upload your own policy documents. Then try an edge case: “Can I store encrypted customer data on my personal laptop since it is encrypted?”
The problem
Policy is unreadableAsk legal
Slow and expensive for every routine question
Ask a chatbot
Hallucinates policy detail, which is worse than no answer
Guess
Informal verbal guidance creates regulatory exposure
SAGE sits between the three: grounded in the actual policy text, automated, auditable, and hardened against people trying to talk it out of its own rules.
What it returns
Structured, cited, scored> I just started 45 days ago. Am I eligible for remote work?
- Answer
- You are not eligible. POL-RW-2025 §2 requires 90-day probation completion.
- Citations
- POL-RW-2025 §2 — Eligibility
- Risk level
- Medium
- Reasoning
- Employee tenure (45 days) is below the 90-day threshold. The request cannot proceed until probation is completed.
- Confidence
- 74 / 100
- Policy tension
- None detected.
Five phases
Prompt to productionArrow keys to step
System prompt design
Find the best prompting strategy for compliance reasoning by testing, not guessing
- 13 techniques on one identical query, so results compare directly
- 7 foundational: zero-shot, few-shot, CoT, step-back, analogical, auto-CoT, generated knowledge
- 5 advanced: decomposition, ensembling, self-consistency, universal self-consistency, self-criticism
- Meta-prompting: model rewrites its own system prompt
Decision
- Chose
- Test all 13, then synthesise
- Over
- Pick chain-of-thought and move on
Because
- Same query across every technique makes the comparison valid
- Structured output (answer, citations, risk, reasoning, confidence) came from the winners
Cost
13 runs of scaffolding before a single line of product code.
- 52%
- zero-shot baseline
- 85%
- format compliance
Architecture
Full request pathResults
Target against actual| Metric | Target | Actual |
|---|---|---|
| Risk classification accuracy | ≥ 87% | ≥ 91% |
| LLM-as-judge score | ≥ 8.5/10 | ≥ 8.5/10 |
| Citation groundedness | 100% | 100% |
| Average confidence | ≥ 70/100 | 82/100 |
| Attack block rate | 100% | 100% |
| Legit query pass rate | 100% | 100% |
| Unit test pass rate | 100% | 100% |
| Policy conflict rules | 5/5 | 5/5 |
Stack
Everything usedModel and agent
- GPT-4o
- LangGraph
- LangChain
- ReAct
Retrieval
- ChromaDB
- text-embedding-3-small
- Hybrid re-ranking
Documents
- pdfplumber
- 3-pass extractor
- Section-boundary chunking
Security
- 52-pattern regex
- Query sanitiser
- Citation verifier
Evaluation
- GPT-4o-mini as judge
- 57-case suite
- pytest
Delivery
- Streamlit
- Docker
- Cloud Run
- Python 3.11